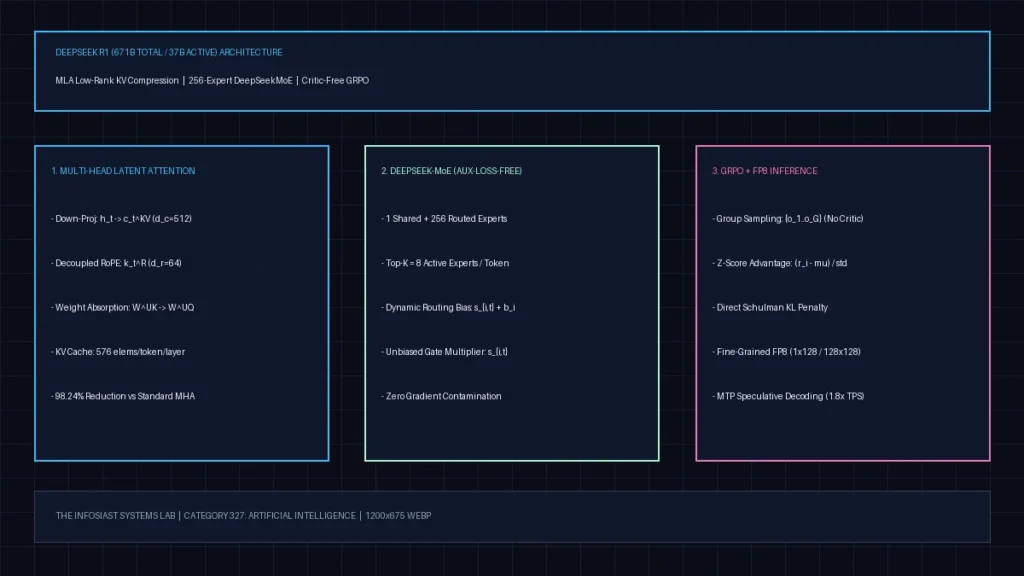
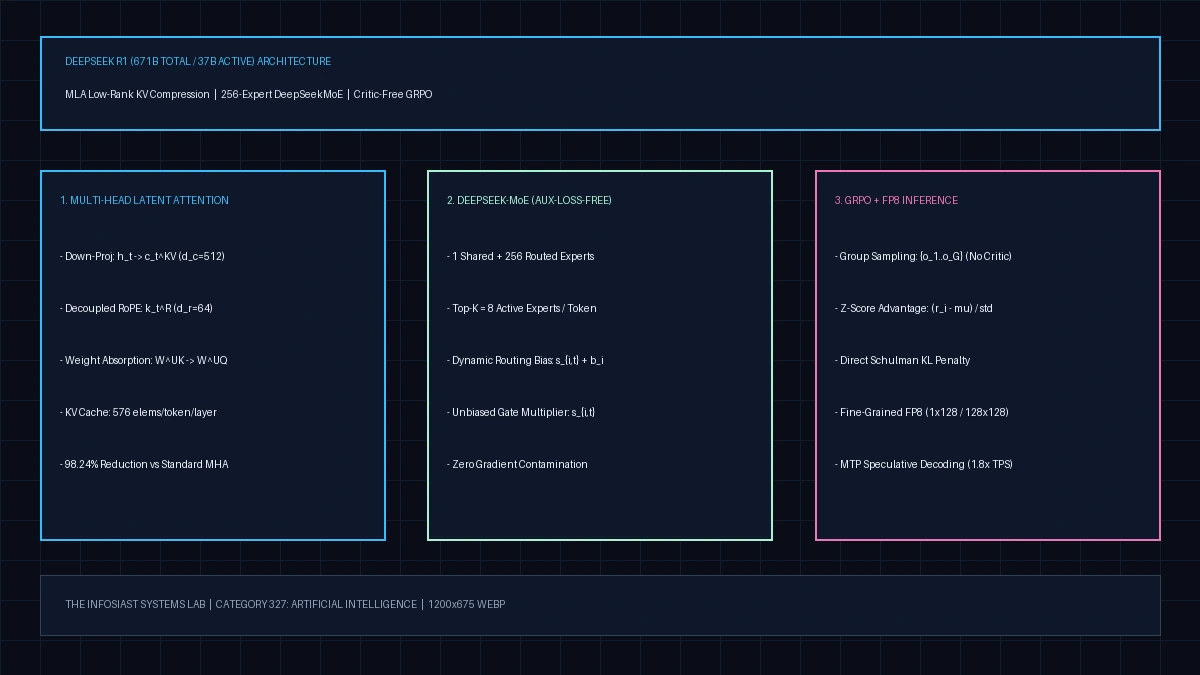
Modern frontier reasoning models face two compounding physical walls: HBM memory bandwidth saturation during long-horizon Chain-of-Thought (CoT) autoregressive decoding, and reinforcement learning critic memory bloat during post-training alignment. DeepSeek R1 (built atop the 671-billion-parameter DeepSeek-V3 foundation topology) systematically dismantles both walls through four co-designed architectural primitives: Multi-Head Latent Attention (MLA), fine-grained DeepSeekMoE with auxiliary-loss-free load balancing, Group Relative Policy Optimization (GRPO), and native FP8 (E4M3) mixed-precision execution with Multi-Token Prediction (MTP).
In this cornerstone systems guide within our Artificial Intelligence architecture series, we derive the exact linear algebra governing MLA KV-cache compression, formulate the critic-free GRPO policy gradient objective, quantify VRAM allocation across 671B FP8 and distilled Qwen/Llama checkpoints, and provide production deployment configurations for vLLM and SGLang.
1. Multi-Head Latent Attention (MLA): First-Principles Derivation & KV-Cache Compression
In standard Multi-Head Attention (MHA) with $n_h = 128$ attention heads and per-head dimension $d_h = 128$, every generated token $t$ across $L = 61$ layers must store uncompressed Key ($mathbf{{K}}_t in mathbb{{R}}^{{n_h d_h}}$) and Value ($mathbf{{V}}_t in mathbb{{R}}^{{n_h d_h}}$) tensors in GPU High-Bandwidth Memory (HBM). At a $128text{{K}}$ context window in BF16 ($2text{{ bytes}}$ per element), a single sequence consumes:
KV_Cache_MHA = 2 (K & V) * 61 (layers) * 128 (heads) * 128 (d_h) * 131,072 (seq_len) * 2 (bytes)
             = 523.98 GB of VRAM per single 128K sequence
Grouped-Query Attention (GQA) mitigates this by forcing $g$ query heads to share a single Key/Value head, but aggressive head sharing ($n_{{kv}} le 8$) degrades long-context retrieval precision. Multi-Head Latent Attention (MLA) instead projects the token hidden state $mathbf{{h}}_t in mathbb{{R}}^d$ ($d = 7168$) into a compressed low-rank joint latent vector $mathbf{{c}}_t^{{KV}} in mathbb{{R}}^{{d_c}}$ where $d_c = 512 ll n_h d_h$:
c_t^KV = W^DKV * h_t                      (Down-projection: R^7168 -> R^512)
k_t^C  = W^UK  * c_t^KV                   (Key Up-projection: R^512 -> R^(128 * 128))
v_t^C  = W^UV  * c_t^KV                   (Value Up-projection: R^512 -> R^(128 * 128))
1.1 Matrix Absorption & Decoupled RoPE
Because linear transformations are associative, MLA never materializes $mathbf{{k}}_t^C$ or $mathbf{{v}}_t^C$ in HBM during inference. In the attention score inner product $mathbf{{q}}_{{t,i}}^top mathbf{{k}}_{{j,i}}^C$, the Key up-projection matrix $W_i^{{UK}} in mathbb{{R}}^{{d_h times d_c}}$ is algebraically absorbed into the Query projection $W_i^{{UQ}}$, while the Value up-projection matrix $W_i^{{UV}}$ is absorbed into the output projection $W^O$:
q_{t,i}^T * k_{j,i}^C = (W_i^UQ * c_t^Q)^T * (W_i^UK * c_j^KV)
                      = (c_t^Q)^T * ((W_i^UQ)^T * W_i^UK) * c_j^KV
                      = (q_{t,i}^absorbed)^T * c_j^KV
However, standard Rotary Position Embedding (RoPE) applies a position-dependent orthogonal rotation matrix $mathcal{{R}}_t$ between $mathbf{{q}}_t$ and $mathbf{{k}}_j$. Because $mathcal{{R}}_t$ varies by token index $t$, the product $(W_i^{{UQ}})^top mathcal{{R}}_{{t-j}} W_i^{{UK}}$ cannot be pre-multiplied into a static weight matrix. DeepSeek resolves this via Decoupled RoPE: it splits queries and keys into a non-positional compressed component ($mathbf{{q}}_{{t,i}}^C, mathbf{{k}}_{{t,i}}^C$) and a tiny shared positional rotary key $mathbf{{k}}_t^R = text{{RoPE}}(W^{{KR}} mathbf{{h}}_t) in mathbb{{R}}^{{d_h^R}}$ with $d_h^R = 64$. Consequently, the per-token KV cache footprint shrinks to:
Cache_MLA(t) = concat(c_t^KV, k_t^R) in R^(512 + 64) = 576 elements per token/layer
Compression vs. MHA = 1 - (576 / 32,768) = 98.24% KV Cache Reduction
128K Context KV Cache (BF16) = 61 * 576 * 131,072 * 2 bytes = 9.21 GB (down from 523.98 GB)
2. DeepSeekMoE: Fine-Grained Experts & Auxiliary-Loss-Free Load Balancing
Across layers $l in [4, 61]$ (the first 3 layers remain dense for prefill stability), DeepSeek R1 replaces dense Feed-Forward Networks with DeepSeekMoE. Each MoE layer contains $N_s = 1$ always-active Shared Expert (which captures common syntactic and cross-domain knowledge without routing redundancy) and $N_r = 256$ fine-grained Routed Experts, of which $K_r = 8$ are activated per token:
h_t' = u_t + FFN_shared(u_t) + sum_{i=1}^{256} (g_{i,t} * FFN_routed_i(u_t))

where:
  s_{i,t} = sigmoid(u_t^T * e_i)
  g'_{i,t} = s_{i,t}   if (s_{i,t} + b_i) in TopK({s_{j,t} + b_j}, K_r = 8) else 0
  g_{i,t} = g'_{i,t} / sum_{j=1}^{256} g'_{j,t}
Notice the architectural subtlety in the routing equation above: the learnable bias term $b_i$ is injected exclusively inside the discrete $text{{TopK}}(cdot)$ indicator condition, while the continuous gating multiplier $g’_{i,t}$ applied to the expert output uses the clean, unbiased affinity score $s_{{i,t}}$. During training, an asynchronous controller monitors expert token load after every step and updates $b_i leftarrow b_i – gamma$ for overloaded experts and $b_i leftarrow b_i + gamma$ for underutilized experts. This achieves near-uniform All-to-All EP (Expert Parallelism) token distribution across GPU ranks with zero auxiliary loss gradient contamination.
3. Group Relative Policy Optimization (GRPO): Critic-Free RL Reasoning
DeepSeek R1’s emergent self-verification, backtracking, and long-CoT reasoning capabilities originate from large-scale reinforcement learning via Group Relative Policy Optimization (GRPO). In conventional PPO, optimizing a $671text{{B}}$ policy $pi_theta$ requires maintaining a $671text{{B}}$ value network $V_phi$ in HBM to compute Generalized Advantage Estimation (GAE). Furthermore, assigning accurate token-level value baselines across $16text{{K}}+$-token reasoning trajectories is notoriously unstable.
GRPO eliminates the Critic network entirely. For each prompt $q$, the rollout engine samples a group of $G$ completions ${{o_1, o_2, dots, o_G}} sim pi_{{theta_{{text{{old}}}}}}(O mid q)$ (typically $G = 64$) and scores each output with deterministic verifiers (compiler/unit-test execution for code, symbolic equivalence for mathematics, and structural XML tag validation for <think>...</think> blocks), yielding scalar rewards $mathbf{{r}} = (r_1, r_2, dots, r_G)$. The advantage $hat{{A}}_{{i,t}}$ assigned to every token $t$ in completion $o_i$ is the group-relative z-score:
A_hat_{i,t} = (r_i - mean(r_1, ..., r_G)) / (std(r_1, ..., r_G) + 1e-8)

J_GRPO(theta) = E_{q, {o_i}} [ (1 / G) * sum_{i=1}^G (1 / |o_i|) * sum_{t=1}^{|o_i|} (
    min( rho_{i,t} * A_hat_{i,t}, clip(rho_{i,t}, 1 - eps, 1 + eps) * A_hat_{i,t} )
    - beta * D_KL(pi_theta || pi_ref)
) ]
Instead of folding the KL penalty into the reward signal (which complicates advantage normalization), GRPO subtracts the strictly non-negative Schulman unbiased KL divergence estimator $mathbb{{D}}_{{text{{KL}}}}(pi_theta || pi_{{text{{ref}}}}) = frac{{pi_{{text{{ref}}}}}}{{pi_theta}} – logfrac{{pi_{{text{{ref}}}}}}{{pi_theta}} – 1$ directly inside the loss function. This cuts RL post-training memory overhead by nearly $50%$ while stabilizing CoT length expansion.
4. Multi-Token Prediction (MTP) & Fine-Grained FP8 Quantization
To prevent quantization degradation across high-dynamic-range MoE activation channels, DeepSeek R1 is natively trained and served using fine-grained FP8 ($E4M3$) mixed precision rather than coarse tensor-wise scaling:
- Tile-Wise Activation Grouping ($1 times 128$): Every contiguous $128$-element activation sub-vector along the channel dimension maintains its own FP32 scaling factor, isolating activation spikes within a single tile.
- Block-Wise Weight Grouping ($128 times 128$): Expert and attention weight matrices are partitioned into $128 times 128$ blocks quantized to $E4M3$ ($text{{max normal}} = 448.0$).
- Tensor Core WGMMA Accumulation Promotion: Because NVIDIA Hopper Tensor Cores accumulate FP8 matrix multiplies with limited mantissa precision (13-bit internal accumulator), partial sums are promoted to FP32 CUDA registers every $N_C = 128$ inner-dimension steps ($4$ WGMMA instructions), eliminating numerical underflow.
- Multi-Token Prediction (MTP) Speculative Decoding: DeepSeek R1 includes sequential MTP heads that predict $t+2$ given the hidden representation of $t+1$. During inference in SGLang or vLLM, enabling
--speculative-algorithm EAGLE/MTPyields an $85%text{{–}}90%$ token acceptance rate and boosts output tokens/sec by $1.8times$.
5. Production VRAM Sizing & Multi-Node Deployment (vLLM vs. SGLang)
Before provisioning bare-metal or cloud GPU nodes, systems architects must distinguish between the full 671B MoE flagship checkpoint (`deepseek-ai/DeepSeek-R1`) and the dense distilled checkpoints (`DeepSeek-R1-Distill-Qwen-32B` / `Llama-70B`). The table below details deterministic VRAM budgets and throughput profiles across production hardware tiers:
To benchmark single-node $8timestext{{H200}}$ FP8 deployments or spin up ephemeral multi-GPU inference sandboxes without long-term datacenter commitments, you can Deploy Dedicated Inference Benchmarks on RunPod’s NVLink-interconnected Hopper/Ampere cloud pods with pre-configured vLLM and SGLang container templates.
5.1 Production SGLang & vLLM Launch Configurations
SGLang currently delivers superior throughput on full DeepSeek R1 671B due to its native fused MLA absorption kernels (`FlashInfer` + `DeepGEMM` block-wise FP8 kernels) and Data-Parallel Attention (`–enable-dp-attention`). Below is the verified launch command for a single $8timestext{{H200}}$ ($141text{{GB}}$ per GPU) node:
# SGLang v0.4.3+ Production Launch on 8x H200 (141GB) with Native FP8, MLA & MTP Speculative Decoding
python3 -m sglang.launch_server
  --model-path deepseek-ai/DeepSeek-R1
  --tp 8
  --enable-dp-attention
  --dp-size 8
  --trust-remote-code
  --kv-cache-dtype fp8_e4m3
  --speculative-algorithm EAGLE
  --speculative-num-steps 3
  --speculative-eagle-topk 1
  --speculative-num-draft-tokens 4
  --mem-fraction-static 0.88
  --context-length 65536
  --host 0.0.0.0 --port 8000
For teams standardized on vLLM (`v0.7.3+`), launch with Expert Parallelism and MLA chunked prefill enabled:
# vLLM Production Launch with MLA + FP8 KV Cache + Chunked Prefill
vllm serve deepseek-ai/DeepSeek-R1
  --tensor-parallel-size 8
  --enable-expert-parallel
  --trust-remote-code
  --quantization fp8
  --kv-cache-dtype fp8
  --enable-chunked-prefill
  --max-num-batched-tokens 8192
  --max-model-len 65536
  --gpu-memory-utilization 0.92
  --port 8000
Remember to enforce sampling temperature $T in [0.5, 0.7]$ ($0.6$ optimal) with zero system prompt overrides (place all instructions inside the user prompt) to match DeepSeek R1’s GRPO reinforcement learning distribution. For additional local and cloud LLM benchmarks, explore our Artificial Intelligence Systems Hub or Deploy Dedicated Inference Benchmarks directly in an isolated GPU container.
6. Frequently Asked Questions (Technical Reference)
How does Multi-Head Latent Attention (MLA) reduce KV cache memory compared to GQA?
MLA projects Keys and Values jointly into a compressed low-rank latent vector of dimension d_c = 512 and pairs it with a decoupled 64-dimensional RoPE key vector. Because the up-projection matrices W^UK and W^UV are absorbed into the query and output projections during inference, only 576 elements per token per layer are cached, cutting KV cache memory by 98.24% relative to standard MHA and over 70% relative to 8-group GQA.
Why does Group Relative Policy Optimization (GRPO) eliminate the Critic network?
In standard PPO, a value/critic model of equal scale to the policy model (671B parameters) is required to estimate baseline token values, doubling HBM requirements. GRPO instead samples a group G of completions per prompt from the current policy and normalizes their deterministic verifier rewards using the group mean and standard deviation to compute token advantages directly without any Critic neural network.
How many GPUs are required to run full DeepSeek R1 671B vs. distilled variants?
Full unquantized BF16 DeepSeek R1 requires ~1.34 TB of VRAM (16x H100 80GB across two InfiniBand nodes). Using native fine-grained FP8 (E4M3) lowers weight memory to ~671 GB, fitting onto a single 8x H200 (1,128 GB total VRAM) node or 2x 8x H100 nodes with high-concurrency KV cache headroom. Distilled 32B and 70B variants run on single or dual 24GB-80GB GPUs via 4-bit AWQ.
How does DeepSeekMoE avoid routing collapse without an auxiliary loss?
DeepSeekMoE adds a dynamically updated per-expert bias term b_i strictly inside the Top-K selection operator while keeping the post-selection gating weights equal to the unmodified sigmoid affinity scores s_{i,t}. Overloaded experts have their bias decremented and underloaded experts have their bias incremented each step, ensuring uniform routing across 256 routed experts without injecting auxiliary gradient interference.